Leetcode Solutions
如何判断区间重叠
vector<int>a, b;
if(max(a[0], b[0]) <= min(a[1], b[1]))
189. Rotate Array
Given an integer array nums, rotate the array to the right by k steps, where k is non-negative.
这个太巧妙了,首先是第一个可能 k > n, n = nums.size() ,这个点我都没注意到
然后是nums[i] = nums[(i+k)%n] 我算了半天没算出来这个公式,把%忘记了sb了,一直在想i+-k+-n。。。
所以最基础O(N)就是新开一个数组,new[(i+k)%n]= nums[i] 然后覆盖一遍
然后可能跟%的思路有关,发现通过三次reverse就能完美达到目标,我感觉因为本来就需要把后面的放前面所以reverse就能达成一部分目的。然后分成两段反转序列就结束了
我不知道数学原理是什么,但是根据答案看结果确实很显而易见。。
n = 7; k = 3;
// 1 2 3 4 5 6 7
// 7 6 5 4 3 2 1

// final: 5 6 7 1 2 3 4
// 7 6 5 || 4 3 2 1
// 5 6 7 || 1 2 3 4
class Solution {
public:
    void rotate(vector<int>& nums, int k) {
        int n = nums.size();
        k %= n;
        reverse(nums.begin(), nums.end());
        reverse(nums.begin(), nums.begin() + k);
        reverse(nums.begin() + k, nums.end());

    }
};
45. Jump Game II
You are given a 0-indexed array of integers nums of length n. You are initially positioned at index 0.
Each element nums[i] represents the maximum length of a forward jump from index i. In other words, if you are at index i, you can jump to any index (i + j) where:
0 <= j <= nums[i]andi + j < n
Return the minimum number of jumps to reach index n - 1. The test cases are generated such that you can reach index n - 1.
这题显而易见的dp
dp思路很好理解,从0到j-1逐步更新状态,优先找到的一定是最小的
class Solution {
public:
    int jump(vector<int>& nums) {
        int n = nums.size();
        vector<int> dp(n, 2e9);
        dp[0] = 0;
        for(int j = 1; j < n; j++){
            for(int i = 0; i < j; i++){
                if(dp[j] < 2e9)
                    break;
                if (i + nums[i] >= j){
                    dp[j] = min(dp[j], dp[i] + 1);
                }
            }
        }
        return dp[n-1];
    }
};
但这题的贪心思路很有意思
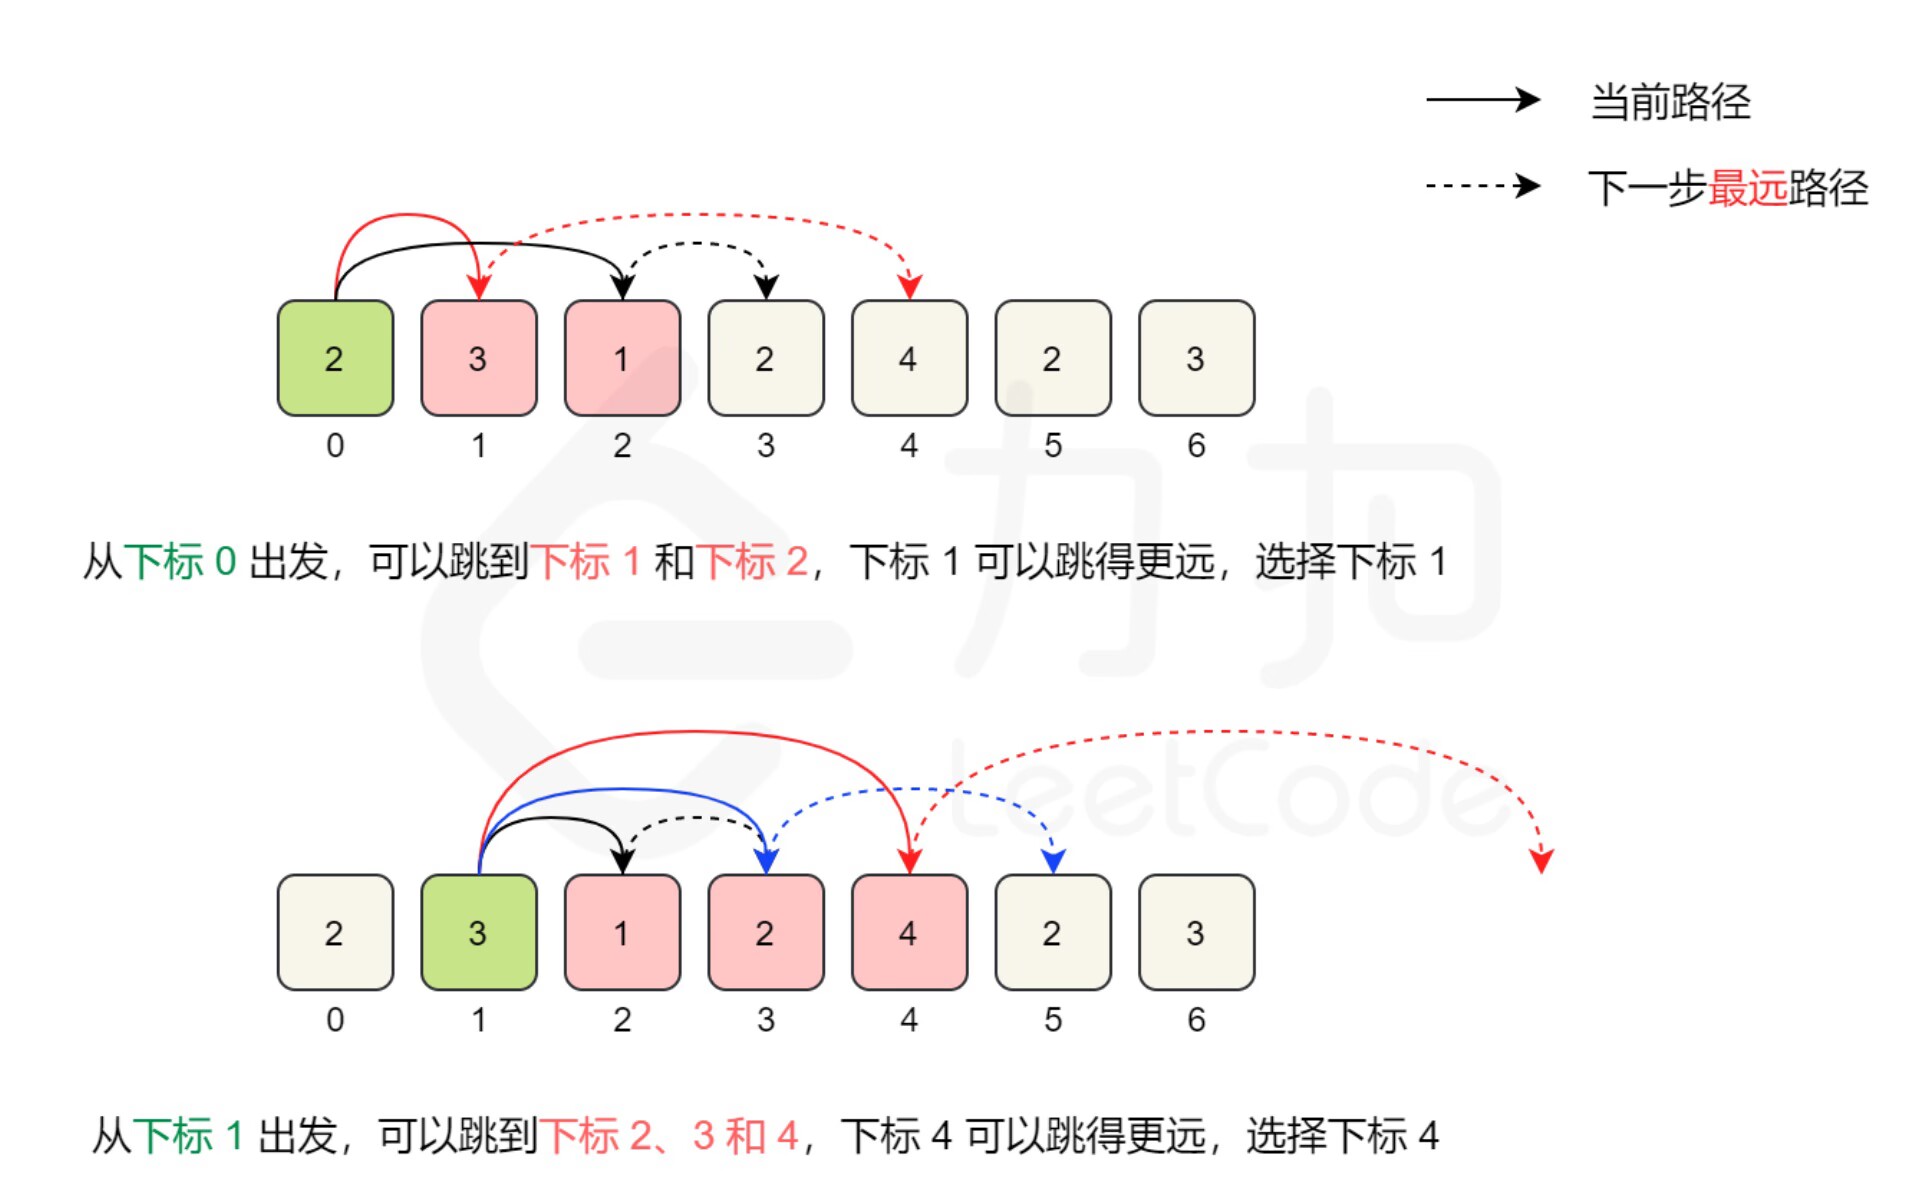
永远选下一个能跳到最远地方的位置
class Solution {
public:
    int jump(vector<int>& nums) {
        int n = nums.size();
        int current = 0, far = 0, jump = 0, next = 0;
        while(current < n-1){
            if (current + nums[current] >= n-1)
            {
                jump++;
                break;
            }
            for(int i = current+1; i <= current+nums[current]; i++){
                if(i + nums[i] > far){
                     far = i + nums[i];
                     next = i;
                }

            }
            current = next;
            jump++;
            far = 0;
        }
        return jump;
    }
};
11. Container With Most Water
You are given an integer array height of length n. There are n vertical lines drawn such that the two endpoints of the ith line are (i, 0) and (i, height[i]).
Find two lines that together with the x-axis form a container, such that the container contains the most water.
Return the maximum amount of water a container can store.
Notice that you may not slant the container.
Example 1:
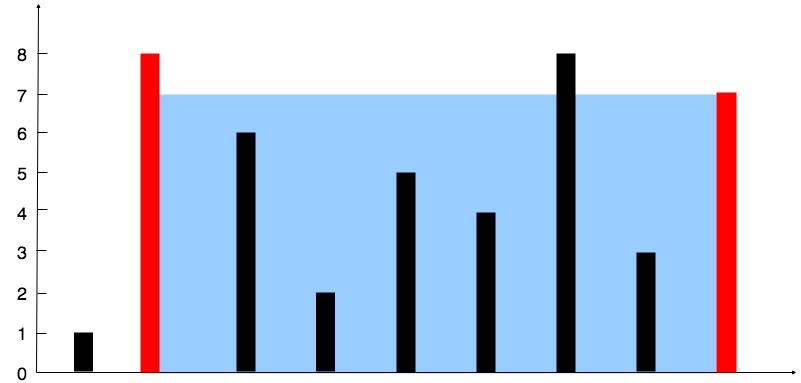
极其巧妙的一道题,首先肯定知道打暴力是O(N^2), 枚举所以可能的长度l一个个搜
但显然太慢了,这题O(N)是可以做的,确实想到了先保证宽度最大然后再一步步搜宽度减少的区间,但我卡在了如何判断h小的指针是左移还是右移我发现写一个简单的判断一定会导致指针原地踏步。
然后本题最精华的地方来了,就是当你发现你要移动h偏小的指针的时候,其实当目前宽度最大的时候他最优的所有解已经被排除了
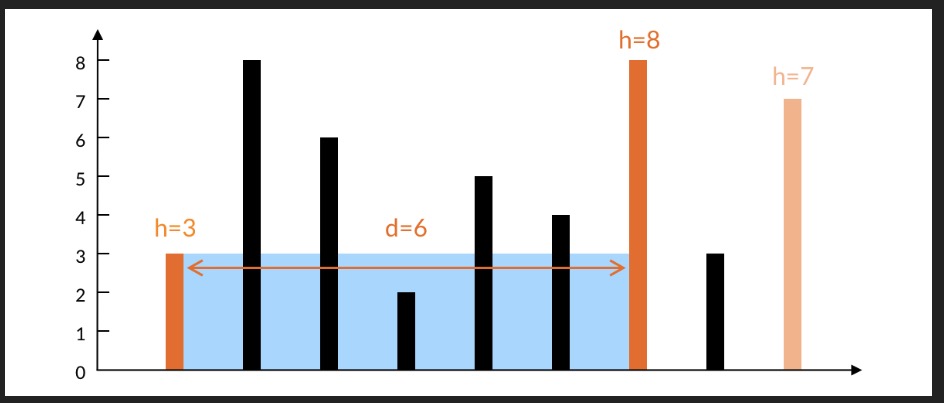
如果选择固定一根柱子,另外一根变化,水的面积会有什么变化吗?稍加思考可得:
当前柱子是最两侧的柱子,水的宽度 d 为最大,其他的组合,水的宽度都比这个小。
- 左边柱子较短,决定了水的高度为 3。如果移动左边的柱子,新的水面高度不确定,一定不会超过右边的柱子高度 7。
- 如果移动右边的柱子,新的水面高度一定不会超过左边的柱子高度 3,也就是不会超过现在的水面高度。
由此可见,如果固定左边的柱子,移动右边的柱子,那么水的高度一定不会增加,且宽度一定减少,所以水的面积一定减少。这个时候,左边的柱子和任意一个其他柱子的组合,其实都可以排除了。也就是我们可以排除掉左边的柱子了。
我当时其实也想了dps搜索,dps(i,j)但我也卡在了状态转移,没有想到其实从宽度最大的时候搜,只要i++或者j—都是排除了当前i或j与任何可能组合得到的情况,当前(i,j) 对于其他(i, 0-j-1)已经是最优解也就是相当于排除了一整列或者一整行。
主要还是没想到最关键的,只要需要移动h小的指针,那他永远只有一种移动方向。
代码实在是没难度
class Solution {
public:
    int maxArea(vector<int>& height) {
        int n = height.size();
        int head = 0, tail = n - 1;
        int max_answer = 0;
        while(head <= tail){
            max_answer = max(max_answer, min(height[head], height[tail]) * (tail - head));
            if (height[head] < height[tail])
                head++;
            else
                tail--;

        }
        return max_answer;
    }
};
63. Unique Paths II
这题炸一看以为是bfs结果我搞错了bfs是一层一层搜索,常用于最短路
- 最短路径
- 最少步数
- 最早到达
- 状态搜索
dfs 一条路走到底, 用于输出所有路径
- 求路径数量(Unique Paths、Decode Ways、Climbing Stairs) → DP
- 求最短步数(Open Lock、Word Ladder、Rotting Oranges) → BFS
- 求所有路径(Path Sum II、Subsets、Permutations) → DFS / 回溯(Backtracking)
回顾一下标准bfs
#include <queue>
using namespace std;

queue<pair<int, int>> q;

const int dx[4] = {-1, 1, 0, 0};
const int dy[4] = {0, 0, -1, 1};

q.push({0, 0});
visited[0][0] = true;

while (!q.empty()) {

    pair<int, int> cur = q.front();
    q.pop();

    int x = cur.first;
    int y = cur.second;

    // 处理当前节点
    cout << x << " " << y << endl;

    for (int i = 0; i < 4; i++) {

        int nx = x + dx[i];
        int ny = y + dy[i];

        if (nx < 0 || nx >= rows || ny < 0 || ny >= cols)
            continue;

        if (visited[nx][ny])
            continue;

        visited[nx][ny] = true;
        q.push({nx, ny});
    }
}
这题正解是dp或者写神秘的记忆化dps,但我觉得那个记忆化dps本质是dp没必要记
我调整边界条件调了一年,我记得搜索系列设计到边界就是容易出错,想清楚再写
class Solution {
public:

    int uniquePathsWithObstacles(vector<vector<int>>& obstacleGrid) {
        int dp[101][101];
        int m = obstacleGrid.size(), n = obstacleGrid[0].size();
        memset(dp, 0, sizeof(dp));
        dp[0][0] = 1;
        for(int i = 0; i < m; i++){
            for(int j = 0; j < n; j++){
                if(obstacleGrid[i][j] == 1)
                        dp[i][j] = 0;
                else{
                    if (i-1<0 && j-1>=0)
                        dp[i][j] = dp[i][j-1];

                    else if (j-1<0 && i-1>=0)
                        dp[i][j] = dp[i-1][j];
                    else if(i-1>=0 && j-1>=0)
                        dp[i][j] = dp[i-1][j] + dp[i][j-1];
                }

            }
        }
        return dp[m-1][n-1];
    }
};
Minimum swaps to sort an array
Given an array arr[] of distinct elements. Find the minimum number of swaps required to sort the array in strictly increasing order.
Examples:
Input: arr[] = [2, 8, 5, 4]
Output:1
Explanation: Swap 8 with 4 to get the sorted array.
这题的描述无敌简单,但实际有点绕。。。我被绕晕了。
这题哈希表的思路我想到了,但我想的有点问题我想的是哈希记录每个数应该去到的位置,结果发现应该哈希的是每个数当前的位置,因为你用另一个list存sort好的顺序不就行了没必要存哈希好的位置啊,主要是需要不断更新原来序列里面每个数当前所在的位置
我也不知道我为啥就卡了,然后就是我以为这题会有优先级,但其实就是每次把本来应该在这个位置的数换到该来的位置就行了我好蠢。。
比如8不等于4,所以把本来在1这个位置的4和当前的8交换位置就行了,不用想有没有贪心之类的优先级,比如我最开始想的只要两个该换位置的刚好匹配才交换之类的。。。
其实每次就是把该在这个位置的数换过来就行了保证一定是对的,如果刚好后面发现不用在动了本来就是最优解,这题写的时候也很绕建议开一个target存这个被交换的数在原序列的位置。。
class Solution {
  public:
    int minSwaps(vector<int>& arr) {
        // Code here
        int ans = 0;
        vector<int>final = arr;
        sort(final.begin(), final.end());
        unordered_map<int, int> now_pos;
        for(int i = 0; i < arr.size(); i++){
            now_pos[arr[i]] = i;
        }
        for (int i = 0; i < arr.size(); i++){
            if(arr[i] != final[i]){
                int target = now_pos[final[i]];
                swap(arr[i], arr[target]);
                ans++;
                now_pos[arr[i]] = i;
                now_pos[arr[target]] = target;
            }
        }
        return ans;
    }
};
1901. Find a Peak Element II
A peak element in a 2D grid is an element that is strictly greater than all of its adjacent neighbors to the left, right, top, and bottom.
Given a 0-indexed m x n matrix mat where no two adjacent cells are equal, find any peak element mat[i][j] and return the length 2 array [i,j].
You may assume that the entire matrix is surrounded by an outer perimeter with the value -1 in each cell.
You must write an algorithm that runs in O(m log(n)) or O(n log(m)) time.
Example 1:
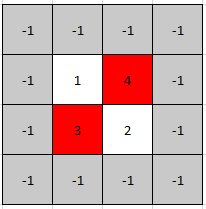
Input: mat = [[1,4],[3,2]]
Output: [0,1]
Explanation: Both 3 and 4 are peak elements so [1,0] and [0,1] are both acceptable answers.
这题又是典型的思路题,就算知道logn是要用二分也完全想不出来。
我觉得这题题解就在复杂度上面,如何满足小于O(mlog(mn)) 的复杂度来实现
首先知道这题要二分,因为涉及比大小+log复杂度大概率二分,问题是怎么二分。首先二分数值的条件是序列有序,但此题很明显只要排序复杂度一定超,所以只有一个思路 二分坐标。
二分坐标之后有什么用呢,怎么保证一定往正确答案移动?这就是卡住我的点就算我二分了row,我也不知道怎么推进,我不知道逻辑在哪里
结果我发现key是二分了一个row之后找到这个row里面最大的列,最大的列保证了一个条件他左右的一定比他小,所以由此再看他这个列上下临界的两个数哪个大,二分往大的那边走,大概思路就这样。。
代码好写,主要是这个思路太抽象了
顺便复习下二分基本写法
int binary_search(int target, vector<int>& nums){
    int l = 0, r = nums.size() - 1;
    while (l <= r){
        int mid = l + (r - l)/2;
        if (nums[mid] == target)
                return mid;
        else if (nums[mid] < target)
            l = mid + 1;
        else r = mid - 1;
    }
}
class Solution {
public:

    vector<int> findPeakGrid(vector<vector<int>>& mat) {

        vector<int> final_pos;
        int m = mat.size(), n = mat[0].size();
        int l = 0, r = m;
        if( m == 1){
            int max = 0;
            int biggest_col;
            for (int i = 0; i < n; i++){
                if(mat[0][i] > max){
                    biggest_col = i;
                    max = mat[0][i];
                }
            }
            return final_pos={0,biggest_col};
        }
        while(l <= r){
            int mid = l + (r - l)/2;
            int max = 0;
            int biggest_col;
            for (int i = 0; i < n; i++){
                if(mat[mid][i] > max){
                    biggest_col = i;
                    max = mat[mid][i];
                }
            }

            if(mid - 1 < 0){ // if can not go up;
                if(mat[mid+1][biggest_col] < mat[mid][biggest_col]){
                    final_pos={mid, biggest_col};
                     break;
                }
                else
                    l = mid + 1;
            }
            else if(mid + 1 >= m){ // if can not go down
                if(mat[mid-1][biggest_col] < mat[mid][biggest_col]){
                    final_pos={mid, biggest_col};
                    break;
                }
                else
                    r = mid - 1;
            }
            else { // can go up and down
                if(mat[mid+1][biggest_col] > mat[mid][biggest_col])
                    l = mid + 1;
                else if (mat[mid-1][biggest_col] > mat[mid][biggest_col])
                    r = mid - 1;
                else  {final_pos={mid, biggest_col}; break;}

            }

        }
        return final_pos;


    }
};
15. 3Sum
Given an integer array nums, return all the triplets [nums[i], nums[j], nums[k]] such that i != j, i != k, and j != k, and nums[i] + nums[j] + nums[k] == 0.
Notice that the solution set must not contain duplicate triplets.
我觉得这题主要需要做过两数之和, 做过才知道这题思路时候
两数之和是先sort然后根据从大到小找到加起来等于target的值,大于target右移 小于target左移
所以这题最好的思路不是暴力枚举i,j,而是枚举target,把nums[i]当成target然后做两数之和就轻松很多了!
正解思路如下,用的也是两数之和的双指针,但这里需要去重所以要写好几个去重条件
class Solution {
public:
    vector<vector<int>> threeSum(vector<int>& nums) {
        sort(nums.begin(), nums.end());
        vector<vector<int>> ans;
        // bind one x, then run two sum
        for (int i = 0; i < nums.size(); i++){
            if(nums[i] > 0)
                break;
            if (i > 0 && nums[i] == nums[i-1]) // same for avoid same numbers
                continue;
            int l = i + 1, r = nums.size() - 1;
            int target = -nums[i];
            while(l<r){
                if(nums[l] + nums[r] == target){
                    ans.push_back({nums[i], nums[l], nums[r]});
                    while(l<r && nums[l] == nums[l+1]) l++;
                    l++;
                    while(l<r && nums[r] == nums[r-1]) r--;
                    r--;
                    // be careful for these, need to avoid same numbers
                }
                else if(nums[l] + nums[r] > target)
                    r--;
                else l++;
            }

        }


        return ans;
    }
};
然后基于两数之和哈希表的暴力解法
首先是两数之和的哈希表解法,这里的巧妙去重在于边加数,边做判断,就能避免没法判断重复数字的问题
class Solution {
public:

    vector<int> twoSum(vector<int>& nums, int target) {
        unordered_map<int, int> m; // key is number, value is index
        for(int i = 0; i < nums.size(); i++){
           int find = target - nums[i];
           if(m.count(find))
                return {i, m[find]};
            else m[nums[i]] = i;
        }
     return {};   // 加这一句
    }
};
这里的优化很多和双指针类似,其实就是个大暴力+双指针也用到的优化
class Solution {
public:
    vector<vector<int>> threeSum(vector<int>& nums) {
        sort(nums.begin(), nums.end());
        vector<vector<int>> ans;
        // bind one x, then run two sum
        for (int i = 0; i < nums.size(); i++){
            if(nums[i] > 0)
                break;
            if (i > 0 && nums[i] == nums[i-1])
                continue;
            unordered_map<int, int> m;
            for (int j = i + 1; j < nums.size(); j++){ // j will not equal to i, find another k
                int target = - (nums[i] + nums[j]);
                if (target > nums[j]){
                    m[nums[j]]=1; continue;
                }

                if (m.count(target)){
                    ans.push_back({nums[i], nums[j], target});
                    while(j+1 < nums.size() && nums[j] == nums[j+1])
                        j++;
                }
                m[nums[j]]=1;
            }
        }
        return ans;
    }
};
1235. Maximum Profit in Job Scheduling
We have n jobs, where every job is scheduled to be done from startTime[i] to endTime[i], obtaining a profit of profit[i].
You’re given the startTime, endTime and profit arrays, return the maximum profit you can take such that there are no two jobs in the subset with overlapping time range.
If you choose a job that ends at time X you will be able to start another job that starts at time X.
Example 1:
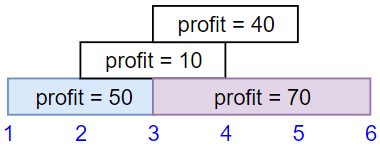
Input: startTime = [1,2,3,3], endTime = [3,4,5,6], profit = [50,10,40,70]
Output: 120
Explanation: The subset chosen is the first and fourth job.
Time range [1-3]+[3-6] , we get profit of 120 = 50 + 70.
首先这题我最开始的思路就暴力dp,以time为dp的状态,这个非常好想,到某个时间寻找以这个时间点为end的job,找到了就判断是否放入队列,判断标准也是找到前一个完全endtime == starttime的job,比较如果强行加入这个job是否会比不加入更优
for (int i min_tim to max_tim)
    find_job = binary_search(i)
    for each find_job
        dp[i] = max(dp[i], dp[i-1], dp[job[find_job].start + job[find_job].val)
然后进一步思考能否不要用时间作为状态转移的条件,改用job的数量?先尝试写一下状态转移方程
dp[1] = 50
dp[2] = max(dp[0]+10, dp[1])
dp[3] = max(dp[1]+40, dp[2])
dp[4] = max(dp[1]+70, dp[3])
问题在如何知道1是怎么转移来的,然后就发现是由第一个endtime≤当前任务的starttime,也就是二分查找,如果找不到任何 就是0
for (int i 0 to n)
    index = lower_bound (job[i].start) // return the index  of job that end <= start
    dp[i] = max(dp[i-1]
class Solution {
public:
    struct Node{
        int start;
        int end;
        int val;
    };
    static bool cmp (Node a, Node b){
        return a.end < b.end;
    }
    int binary_search(int target, vector<Node>& job){ // find the fisrt index that x.end == target

        int l = 0, r = job.size() - 1;
        while(l <= r){
            int mid = l + (r - l)/2;
            if(job[mid].end <= target)
                l = mid + 1;
            else
                r = mid - 1;
        }
        return r;

    }
    int jobScheduling(vector<int>& startTime, vector<int>& endTime, vector<int>& profit) {
        int n = startTime.size();

        vector<Node>job;
        int min_time = (1<<29), max_time = 0;
        for(int i = 0; i < n; i++){
            job.push_back({startTime[i],endTime[i], profit[i]});
            min_time = min (min_time, startTime[i]);
            max_time = max (max_time, endTime[i]);
        }
        sort(job.begin(), job.end(), cmp);
        vector<int>dp (n+1, 0);
        for(int i = 0; i < n; i++){
            int target = job[i].start;
            int find_job = binary_search(target, job);
            if(find_job < 0){ // even smallest can not be found
                dp[i] = max(dp[i], job[i].val);
            }
            else if(job[find_job].start == target){ // every job that ends at startime should be considered
                while(find_job < n && job[find_job].start == target){
                    dp[i] = max(dp[i], dp[find_job] + job[i].val);
                    find_job++;
                }
            }
            else{ // can found the first one that <= startime
                 dp[i] = max(dp[i], dp[find_job] + job[i].val);
            }

            if(i-1>=0)
                dp[i] = max(dp[i], dp[i-1]);
        }
        return dp[n-1];
    }
};
639. Decode Ways II
A message containing letters from A-Z can be encoded into numbers using the following mapping:
'A' -> "1"
'B' -> "2"
...
'Z' -> "26"
To decode an encoded message, all the digits must be grouped then mapped back into letters using the reverse of the mapping above (there may be multiple ways). For example, "11106" can be mapped into:
"AAJF"with the grouping(1 1 10 6)"KJF"with the grouping(11 10 6)
Note that the grouping (1 11 06) is invalid because "06" cannot be mapped into 'F' since "6" is different from "06".
In addition to the mapping above, an encoded message may contain the '*' character, which can represent any digit from '1' to '9' ('0' is excluded). For example, the encoded message "1*" may represent any of the encoded messages "11", "12", "13", "14", "15", "16", "17", "18", or "19". Decoding "1*" is equivalent to decoding any of the encoded messages it can represent.
Given a string s consisting of digits and '*' characters, return the number of ways to decode it.
Since the answer may be very large, return it modulo 109 + 7.
一个比较好设计状态的dp但是我还是想了半天如何不算重复,我的思路是只有10到26这范围可以产生新的破解,其他都只有一种破解办法,所以每当加入一个新的数字,判断是否可以和前一位组成10-26范围的数,如果不行就只有单个单个算的办法,如果可以就算和前面一个数产生了多少新的组合,注意特判2,2只有1-6符合我忘记这个了错了两次都这里错的。其他就是注意开longlong和取模,我压根没看到取模。。。。
ll judge_single_ch(char x){
        if (x == '0')
            return 0;
        else if (x >= '1' && x <= '9')
            return 1;
        else
            return 9;

    }
ll judge_double_ch(char x0, char x1){
    if( x0 == '0')
        return 0;
    else if (x1 == '0') {
        if (x0 == '*')
            return 2;
        else if(x0 >= '1' && x0 <= '2')
            return 1;
        else return 0;
    }
    else {
        if( x0 == '1'){
            if(x1 == '*')
                return 9;
            else return 1;
        }
        else if (x0 == '2'){
            if(x1 == '*')
                return 6;
            else if ( x1 >= '1' && x1 <= '6') // 这个地方太坑了坑我两次
                return 1;
            else return 0;
        }
        else if(x0 == '*'){
            if( x1 == '*')
                return (9+6);
            else if ( x1 >= '1' && x1 <= '6') // 这个地方太坑了坑我两次
                return 2;
            else return 1;
        }
        else return 0;
    }
推导公式没很大难度,我一开始总想着先把单个全部算再算有无两个的组合后来发现这是dp肯定要从前一个状态推就顺理成章写出来了草
for(int i = 0; i < s.size(); i++){
      if(i >= 2){
          dp[i] = (dp[i-1] * judge_single_ch(s[i]) + dp[i-2] * judge_double_ch(s[i-1], s[i])) % mod;
      } else if(i == 1)
          dp[i] = (dp[i-1] * judge_single_ch(s[i]) + judge_double_ch(s[i-1], s[i])) % mod;
      else dp[i] = judge_single_ch(s[i]);
}
Longest Subarray with Sum K
Given an array arr[] containing integers and an integer k, your task is to find the length of the longest subarray where the sum of its elements is equal to the given value k. If there is no subarray with sum equal to k, return 0.
这题前缀和无比容易想到,我主要是犯蠢了没处理好重复结果的前缀和,实际由于求最大的只需要记录最早出现的前缀和的位置,因为我们枚举j一直往后面扫,只需要找在j前面的i满足sum[j]-sum[i-1]=k ,我之前不仅没处理这个还想麻烦了要找k+sum[i] 和 sum[i]-k。。。
class Solution {
  public:
    int longestSubarray(vector<int>& arr, int k) {
        // code here
        int n = arr.size();
        int sum = 0;
        unordered_map<int, int> m;
        int longest = 0;
        m[0] = 0;
        // find two elements in sum that difference of two items equals to k, only need to find j that less than i
        for(int i = 1; i <= n; i++){
            sum += arr[i-1];
            int target = sum - k;
            if(m.count(target))
                longest = max(longest, i-m[target]);
            if(!m.count(sum))
                m[sum] = i;

        }
        return longest;

    }
};
如果用unordered_map<int ,vector<int>>m, 要考虑严格判断当找sum[j]= sum[i-1]+k,j>i-1 ,这里注意前缀和j可以等于i所以条件是j>i-1
class Solution {
public:
    int subarraySum(vector<int>& nums, int k) {
        int n = nums.size();
        vector<int> sum(n+1, 0);
        unordered_map<int, vector<int>> m;
        sum[0] = 0;
        m[sum[0]].push_back(0);
        for(int i = 1; i <= n ;i++){
            sum[i] = sum[i-1] + nums[i-1];
            m[sum[i]].push_back(i);

        }
        int ans = 0;
        // find two elements in sum that difference of two items equals to k
        for(int i = 0; i <= n; i++){

            int target = k + sum[i];
            if(m.count(target)){
                for (auto& x : m[target])
                    if(x > i)// we treat i as k-1 so only j > i is enough
                        ans ++;
            }

        }
        return ans;
    }
};
239. Sliding Window Maximum
You are given an array of integers nums, there is a sliding window of size k which is moving from the very left of the array to the very right. You can only see the k numbers in the window. Each time the sliding window moves right by one position.
Return the max sliding window.
Example 1:
Input: nums = [1,3,-1,-3,5,3,6,7], k = 3
Output: [3,3,5,5,6,7]
Explanation:
Window position                Max
---------------               -----
[1  3  -1] -3  5  3  6  7       3
 1 [3  -1  -3] 5  3  6  7       3
 1  3 [-1  -3  5] 3  6  7       5
 1  3  -1 [-3  5  3] 6  7       5
 1  3  -1  -3 [5  3  6] 7       6
 1  3  -1  -3  5 [3  6  7]      7
这题的暴力是最大堆,顺便复习了最大堆写法,大概就是查一下最大堆堆顶,只要堆顶的index不超过当前区间,就是当前的最大值,如果index已经比当前的区间小了,就不断pop直到找到下一个index不超过区间的值。
代码复习堆的写法
class Solution {
public:
    struct Node{
        int index;
        int val;
    };
    struct cmp {
    bool operator()(const Node& a, const Node& b) {
        return a.val < b.val;
    }

};
    vector<int> maxSlidingWindow(vector<int>& nums, int k) {
        priority_queue<Node, vector<Node>, cmp> q;
        int slide_head = 0, slide_tail = k-1;
        for(int i = 0; i < k; i++){
            q.push({i, nums[i]});
        }
        vector<int> ans;
        while(!q.empty()){
            while(q.top().index < slide_head){
                q.pop();
            }
            ans.push_back(q.top().val);
            slide_head++; slide_tail++;
            if(slide_tail == nums.size())
                break;
            q.push({slide_tail, nums[slide_tail]});

        }
        return ans;

    }
};
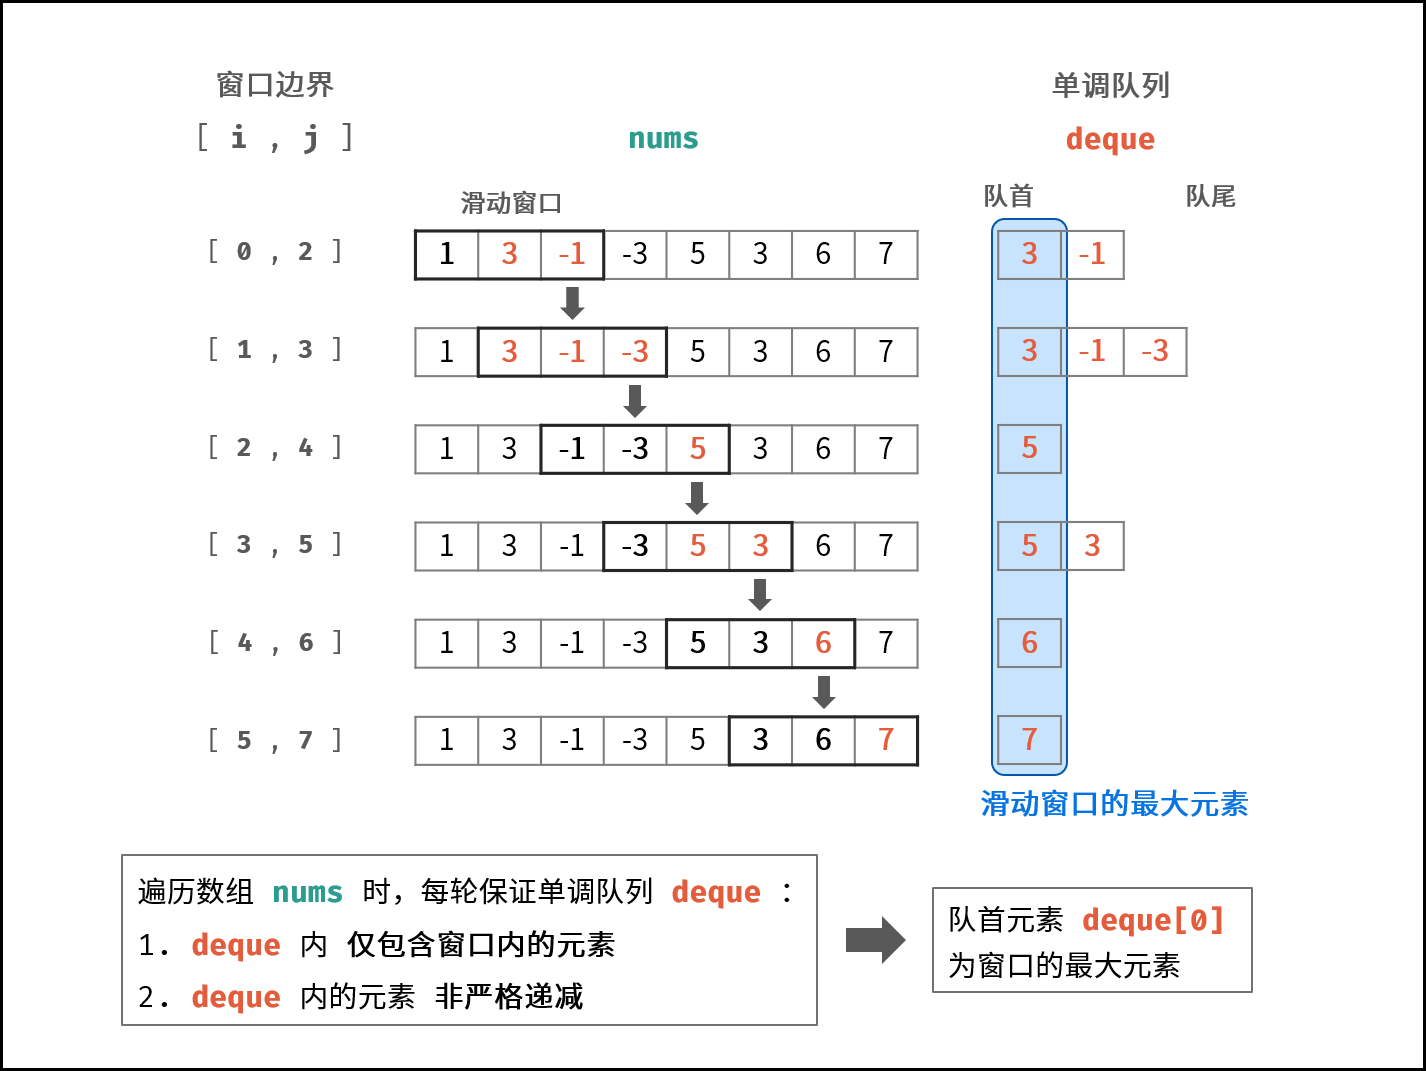
比较巧妙的做法是用双端队列实现单调队列,注意到每次加入一个新的元素时候,若q已经有的元素比当前新元素小了,就把所有小于的元素全部踢掉,手动维护一个单调递减序列,队头的front元素永远是最大的,进元素永远从back进
class Solution {
public:
    vector<int> maxSlidingWindow(vector<int>& nums, int k) {
        deque<int> q;
        for(int i = 0; i < k; i++){
            while(!q.empty() && q.back() < nums[i]){
                    q.pop_back();
            }
            q.push_back(nums[i]);
        }
        vector<int> ans;
        ans.push_back(q.front());
        int slide_head = 1, slide_tail = k;
        while(slide_tail < nums.size()){
            if(q.front() == nums[slide_head-1])
                q.pop_front();
             while(!q.empty() && q.back() < nums[slide_tail]){
                    q.pop_back();
            }
            q.push_back(nums[slide_tail]);
            ans.push_back(q.front());
            slide_head++;
            slide_tail++;

        }

        return ans;

    }
};
42. Trapping Rain Water
Given n non-negative integers representing an elevation map where the width of each bar is 1, compute how much water it can trap after raining.
Example 1:
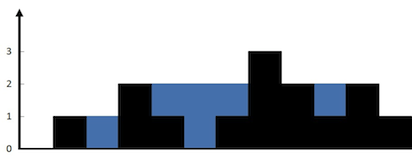
Input: height = [0,1,0,2,1,0,1,3,2,1,2,1]
Output: 6
Explanation: The above elevation map (black section) is represented by array [0,1,0,2,1,0,1,3,2,1,2,1]. In this case, 6 units of rain water (blue section) are being trapped.
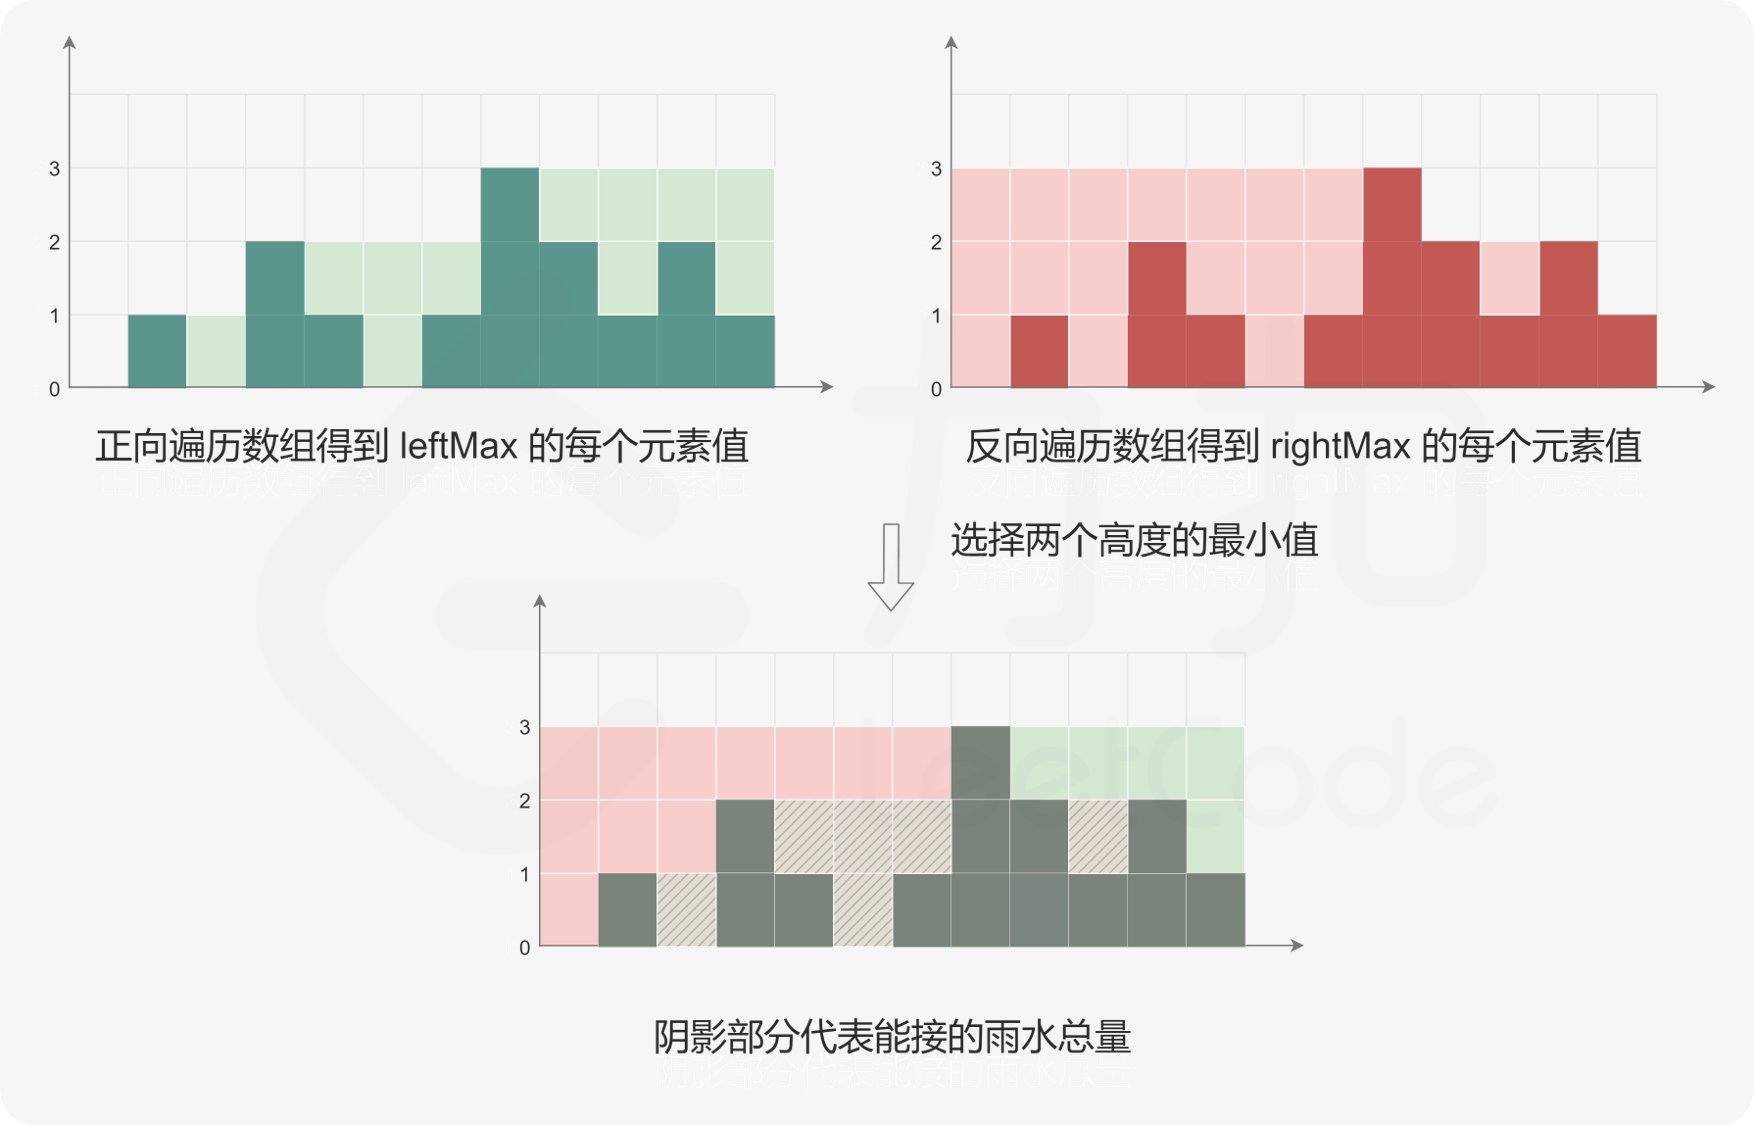
神奇解法1,类似前缀和的dp, 左扫一次右扫一次记录max
class Solution {
public:

    int trap(vector<int>& height) {
        int n = height.size();
        int ans = 0;
        vector<int>left_max(n);
        vector<int>right_max(n);
        left_max[0] = height[0];
        right_max[n-1] = height[n-1];
        for(int i = 1; i < n; i++)
            left_max[i] = max(left_max[i-1], height[i]);
        for(int i = n-2; i>= 0 ;i--)
            right_max[i] = max(right_max[i+1], height[i]);
        for(int i = 0; i < n; i++)
            ans += min(left_max[i], right_max[i]) - height[i];


        return ans;
    }
};
还有解法2单调栈,我说实话这个太巧妙了没想到要考虑两个栈里面的元素,只pop 栈顶。。
这个不好记总之推比较麻烦
class Solution {
public:

    int trap(vector<int>& height) {
        int n = height.size();
        int ans = 0;
        stack<int> st;
        for (int i = 0; i < n; i++){
            while(!st.empty() && height[i] > height[st.top()]){
                int previous_water = st.top();
                st.pop();
                if(st.empty())
                    break;
                int left = st.top();
                int now_width = i - left - 1;
                int now_height = min(height[i], height[left]) - height[previous_water];
                ans += now_width * now_height;
            }
            st.push(i);
        }


        return ans;
    }
};
76. Minimum Window Substring
Given two strings s and t of lengths m and n respectively, return the minimum window *substring of s such that every character in t (including duplicates) is included in the window. If there is no such substring, return the empty string* "".
The testcases will be generated such that the answer is unique.
Example 1:
Input: s = "ADOBECODEBANC", t = "ABC"
Output: "BANC"
Explanation: The minimum window substring "BANC" includes 'A', 'B', and 'C' from string t.
鉴定为屎题,其实就是两个指针不断变化去扫所有满足条件的子区间,然后这两个指针不断变化的条件写了一年。。。
class Solution {
public:
    int freq[53];
    int missing_count;
    set<char> all_char;
    string substring;
    string ans;
    // freq[c] > 0  → 还缺 c
    // freq[c] == 0 → c 数量刚好满足
    // freq[c] < 0  → c 有多余
    int turn(char x) {
        if (x >= 'A' && x <= 'Z')
            return x - 'A';
        else
            return x - 'a' + 27;
    }

    int find_next_head(string s, int current_head) {
        int i = current_head + 1;

        if (current_head != -1) {
            freq[turn(s[current_head])]++;

            // 0 -> 1,说明这个字符从满足变成不满足
            if (freq[turn(s[current_head])] == 1)
                missing_count++;

            substring.erase(0, 1);
        }

        while (i < s.size()) {
            if (!all_char.count(s[i])) {
                i++;
                substring.erase(0, 1);
            }
            else if (freq[turn(s[i])] < 0) {
                freq[turn(s[i])]++;
                i++;
                substring.erase(0, 1);
            }
            else {
                break;
            }
        }

        return i == s.size() ? -1 : i;
    }

    int find_next_tail(string s, int current_tail) {
        int i = current_tail;

        while (missing_count > 0) {
            i++;

            if (i == s.size())
                return -1;

            substring += s[i];

            freq[turn(s[i])]--;

            // 1 -> 0,说明这一种字符刚刚满足要求
            if (freq[turn(s[i])] == 0)
                missing_count--;
        }

        return i;
    }

    string minWindow(string s, string t) {
        memset(freq, 0, sizeof(freq));
        missing_count = 0;
        all_char.clear();
        substring.clear();
        ans.clear();

        for (int i = 0; i < t.size(); i++) {
            // 第一次出现这种字符
            if (freq[turn(t[i])] == 0)
                missing_count++;

            freq[turn(t[i])]++;
            all_char.insert(t[i]);
        }

        int head = find_next_head(s, -1);

        if (head == -1)
            return "";

        int tail = find_next_tail(s, head - 1);

        if (tail == -1)
            return "";

        ans = substring;

        while (tail < s.size() && head != -1 && tail != -1) {
            head = find_next_head(s, head);
            tail = find_next_tail(s, tail);

            if (head == -1 || tail == -1)
                break;

            if (ans.size() > substring.size())
                ans = substring;
        }

        return ans;
    }
};
2055. Plates Between Candles
There is a long table with a line of plates and candles arranged on top of it. You are given a 0-indexed string s consisting of characters '*' and '|' only, where a '*' represents a plate and a '|' represents a candle.
You are also given a 0-indexed 2D integer array queries where queries[i] = [lefti, righti] denotes the substring s[lefti...righti] (inclusive). For each query, you need to find the number of plates between candles that are in the substring. A plate is considered between candles if there is at least one candle to its left and at least one candle to its right in the substring.
- For example,
s = "||**||**|*", and a query[3, 8]denotes the substring"*||*****|". The number of plates between candles in this substring is2, as each of the two plates has at least one candle in the substring to its left and right.
Return an integer array answer where answer[i] is the answer to the ith query.
Example 1:
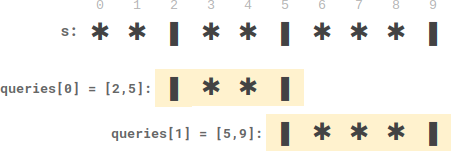
Input: s = "**|**|***|", queries = [[2,5],[5,9]]
Output: [2,3]
Explanation:
- queries[0] has two plates between candles.
- queries[1] has three plates between candles.
很容易搞错的一道题,本来以为是简单前缀和,结果每次区间都要考虑左边和右边的l的index,然后再根据前缀和计算
class Solution {
public:
    void print_vector(vector<int> &v){
        for(int x : v)
            cout<<x <<' ';
        cout<<endl;
    }
    vector<int> platesBetweenCandles(string s, vector<vector<int>>& queries) {
        int n = s.size();
        int previous = -1;
        vector<int> sum(n+1 ,0);
        vector<int> near_right_l(n ,-1);
        vector<int> near_left_l(n ,-1);
        vector<int> ans;
        for(int i = 0; i < n; i++){
            char x = s[i];
            if( x == '*' )
                sum[i+1] = sum[i] + 1;
            else sum[i+1] = sum[i];
            if(x == '|'){
                if(previous == -1){
                    previous = i;
                    for(int j = 0; j <= i; j++)
                        near_right_l[j] = i;
                }
                else {
                    for(int j = previous + 1; j <= i; j++)
                        near_right_l[j] = i;
                    previous = i;
                }
            }

        }
        previous = -1;
        for(int i = n-1; i >= 0; i--){
            char x = s[i];
            if(x == '|'){
                if(previous == -1){
                    previous = i;
                    for(int j = n-1; j >= i; j--)
                        near_left_l[j] = i;
                }
                else {
                    for(int j = previous -1; j >= i; j--)
                        near_left_l[j] = i;
                    previous = i;
                }
            }

        }
        // print_vector(sum);
        // print_vector(near_left_l);
        // print_vector(near_right_l);
        for(auto &x : queries){
            int left_l = near_right_l[x[0]];
            int right_l =near_left_l[x[1]];
            if(left_l >= right_l || right_l == -1 || left_l == -1){
                ans.push_back(0);
                continue;
            }

            int answer = sum[right_l+1] - sum[left_l];
            ans.push_back(answer);
        }

        return ans;


    }
};